
built-in
hundreds of apps
image generation, video, audio, chat, search, and more. run any model with a single API call. pay per run, no subscriptions.
apps
399 apps across image, video, audio, chat, 3d and search. one key, pay per run, zero vendor lock-in.
Professional multimodal video generation from text, images, video, and audio references using ByteDance's Seedance 2.5 model via BytePlus ARK API. Supports up to 4K (10-bit color), durations up to 30s, MOV output, and multimodal reference-to-video with synchronized audio.
Generate talking head videos from a portrait image with text or audio-driven speech
Veo 3.1 Fast via Vertex AI - Generate videos from text prompts or images with optional audio
A unified image editor that allows users to generate images by combining any subject with any style efficiently, preserving identity and consistency.
falai/minimax-h3-max-styles
stylized 768p video with audio from a prompt or first-frame image using fal's minimax h3 max style pipelines. vhs, hand-drawn, 16-bit pixel, retro 70s toon, low-poly.
falai/minimax-h3-max-insert-video
insert a newly generated scene into an existing video with minimax h3 max via fal. pick where the scene starts and where the original resumes; guide it with a prompt and references.
falai/minimax-h3-max-3d-to-video
turn a blender or 3d previs render into photorealistic video with minimax h3 max via fal. layout, camera and timing follow the input; optional reference images set the look.
falai/minimax-h3-max-recast
replace the people in a video with those in reference photos using minimax h3 max via fal. keeps motion, camera, cuts and audio. up to 4 people, 768p or 1080p.
falai/minimax-h3-max-relight
relight an existing video from a lighting sphere reference image with minimax h3 max via fal. keeps subjects, motion, camera and audio; output 480p to 2k.
falai/minimax-h3-max-lip-sync
animate a portrait image to speak an audio track with minimax h3 max via fal. output matches the audio length (5s to 15 min), 480p to 2k, optional transcription guidance.
falai/minimax-h3-max-camera-controls
turn a single image into a video with keyframed camera orbit, elevation and distance using minimax h3 max via fal. the scene stays frozen; only the camera moves.
falai/minimax-h3-max-extend-video
extend an existing video with new prompt-guided footage using minimax h3 max via fal. 1-15s of continuation, 480p to 2k, optional audio references.
falai/minimax-h3-max-turbo-extend-video
extend an existing video with new prompt-guided footage using minimax h3 max turbo via fal. 1-15s of continuation, 480p to 2k, optional audio references.
falai/minimax-h3-max-turbo
minimax h3 max turbo via fal, the faster, cheaper h3 max variant. text-to-video and image-to-video with first/last frame, 480p/768p/1080p, 1-15s, prompt expansion, audio pinning.
falai/flux-3-max
flux 3 max, post-trained flux 3 video by fal and black forest labs. text-to-video, image-to-video with end frame, keyframes-to-video. 720p or 1080p, 5-20s, native audio.
melious/deepseek-v4-1-flash-1017
deepseek v4.1 flash 1017 — the october 2026 refresh of the 552b multimodal moe with 1m context, image input and controllable reasoning. via the melious api.
google/analytics
read google analytics 4 properties and run traffic, acquisition and realtime reports
google/search-console
read search console performance, url index status, and sitemaps for your verified sites
fish-audio/drama-3
fish audio drama 3 text to speech. direct the delivery in plain language, add laughs and sighs, clone a voice from a clip, or voice a dialogue. 80+ languages.
google/gemini-4-argon
gemini 4 argon via vertex ai — google's flagship model for deep, multi-step work in coding, finance, law, security and science. 1m token context, thinking levels low to high.
openai/gpt-6-sol
gpt-6 sol — openai's gpt-6 mid-tier model, superseded by gpt-6.1 sol. 1m context, 128k output, reasoning effort none to max, vision, file input and tool use via the responses api. direct api.
openai/gpt-6-luna
gpt-6 luna — openai's most efficient model for focused, high-volume tasks. 1m context, 128k output, reasoning effort none to max, vision, file input and tool use via the responses api. direct api.
openai/gpt-6-1-sol
gpt-6.1 sol — openai's near-astra flagship at a fraction of the cost. 1m context, 128k output, reasoning effort low to max, vision, file input and tool use via the responses api. direct api.
anthropic/claude-fable-5-1
claude fable 5.1 — anthropic's most capable model for demanding reasoning and long-horizon agents. 1m context, 128k output, always-on thinking with effort, vision, tool use. direct api.
anthropic/claude-haiku-5-5
claude haiku 5.5 — anthropic's fastest, lowest-cost claude for high-volume and latency-sensitive work. 1m context, 128k output, adaptive thinking, vision, tool use. direct api.
anthropic/claude-sonnet-5-5
claude sonnet 5.5 — anthropic's fastest frontier sonnet for coding, agents and everyday work. 1m context, 128k output, adaptive thinking with effort, vision, tool use. direct api.
anthropic/claude-opus-5-5
claude opus 5.5 — anthropic's default opus for long-running agentic coding and knowledge work. 1m context, 128k output, adaptive thinking with effort, vision, tool use. direct api.
meta/muse-wonder-1-0
muse wonder 1.0 — meta's most capable model for coding and long-horizon agents. 1m context, reasoning minimal to max, image, video, audio and pdf input, tools. direct api.
vllm-sr/d3
the largest decision 3.0 model from vllm semantic router. send text, images and videos with typed questions (choice, score, yes/no); get a probability for every answer.
vllm-sr/d3-flash
the 9b decision 3.0 model from vllm semantic router. send text, images and videos with typed questions (choice, score, yes/no); get a probability for every answer.
vllm-sr/d3-mini
the 4b decision 3.0 model from vllm semantic router. send text, images and videos with typed questions (choice, score, yes/no); get a probability for every answer.
vllm-sr/d3-nano
the 2b decision 3.0 model from vllm semantic router. send text, images and videos with typed questions (choice, score, yes/no); get a probability for every answer.
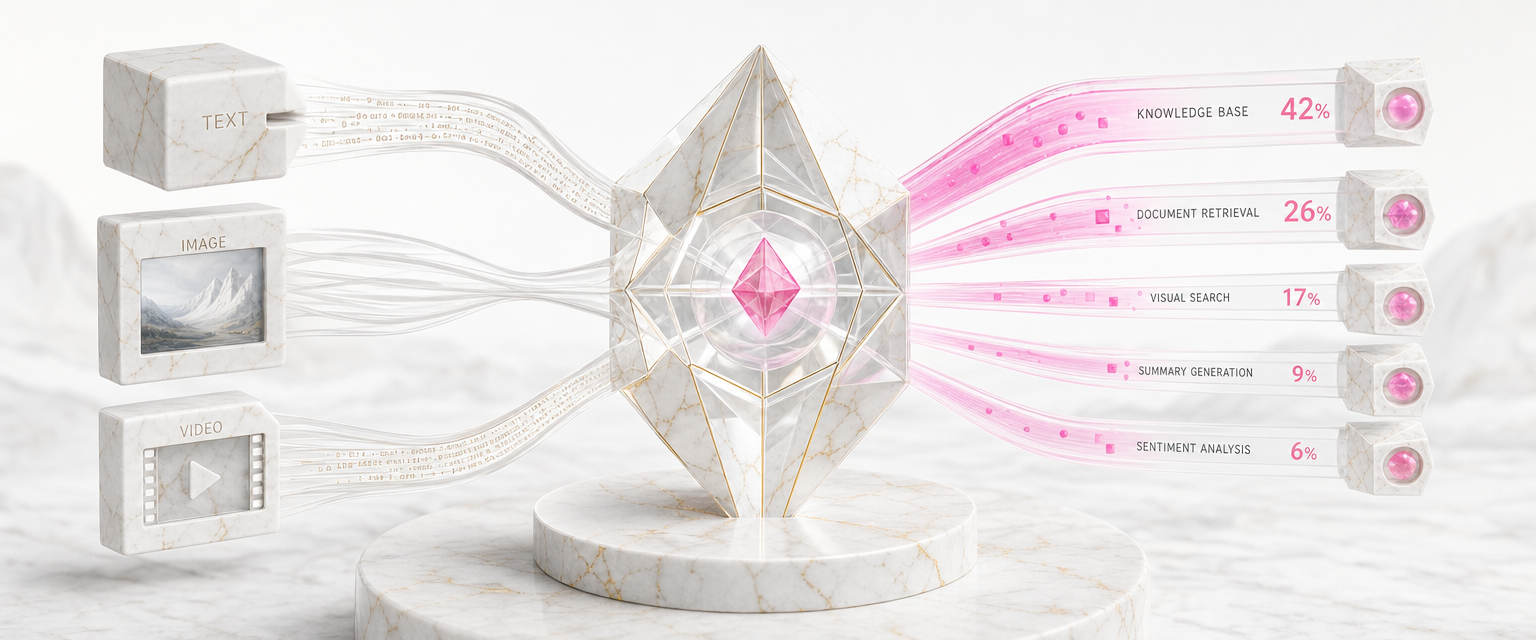
vllm-sr/d3-lite
the 0.8b decision 3.0 model from vllm semantic router. send text, images and videos with typed questions (choice, score, yes/no); get a probability for every answer.
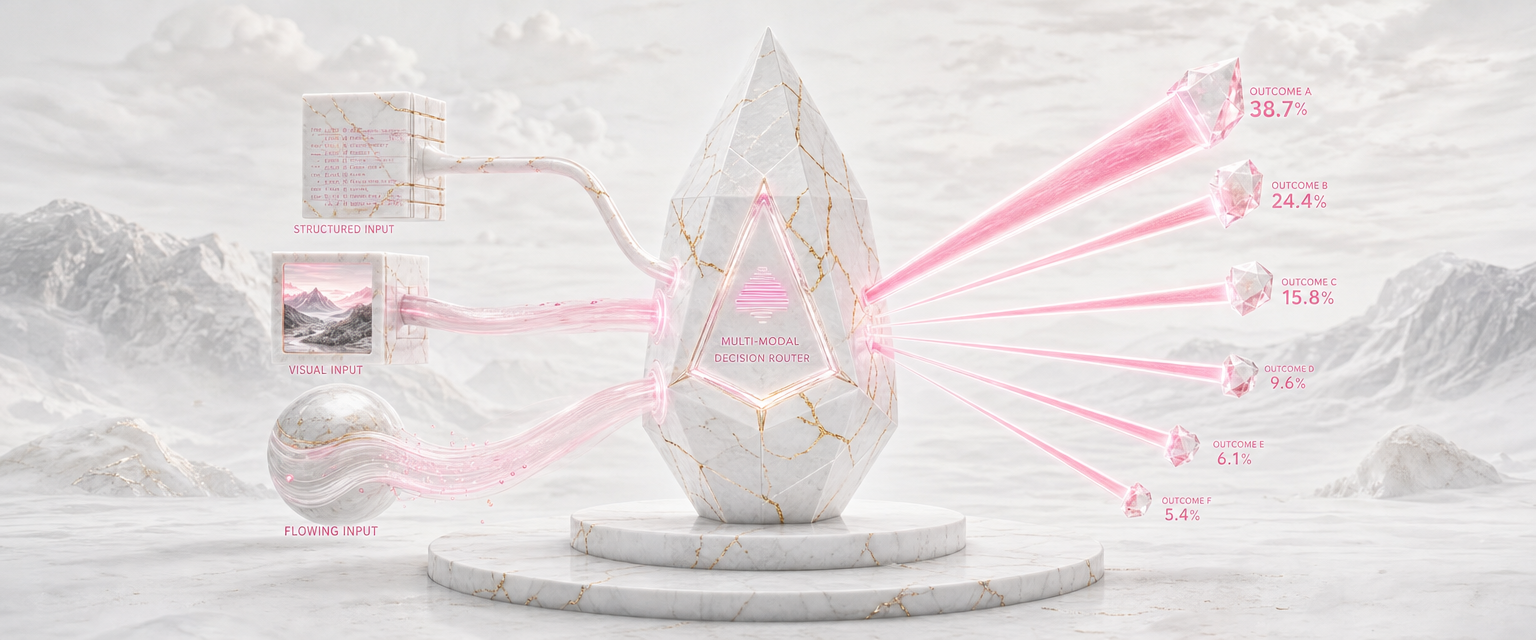
vllm-sr/d3-edge
the smallest and fastest decision 3.0 model from vllm semantic router. send text, images and videos with typed questions (choice, score, yes/no); get a probability for every answer.
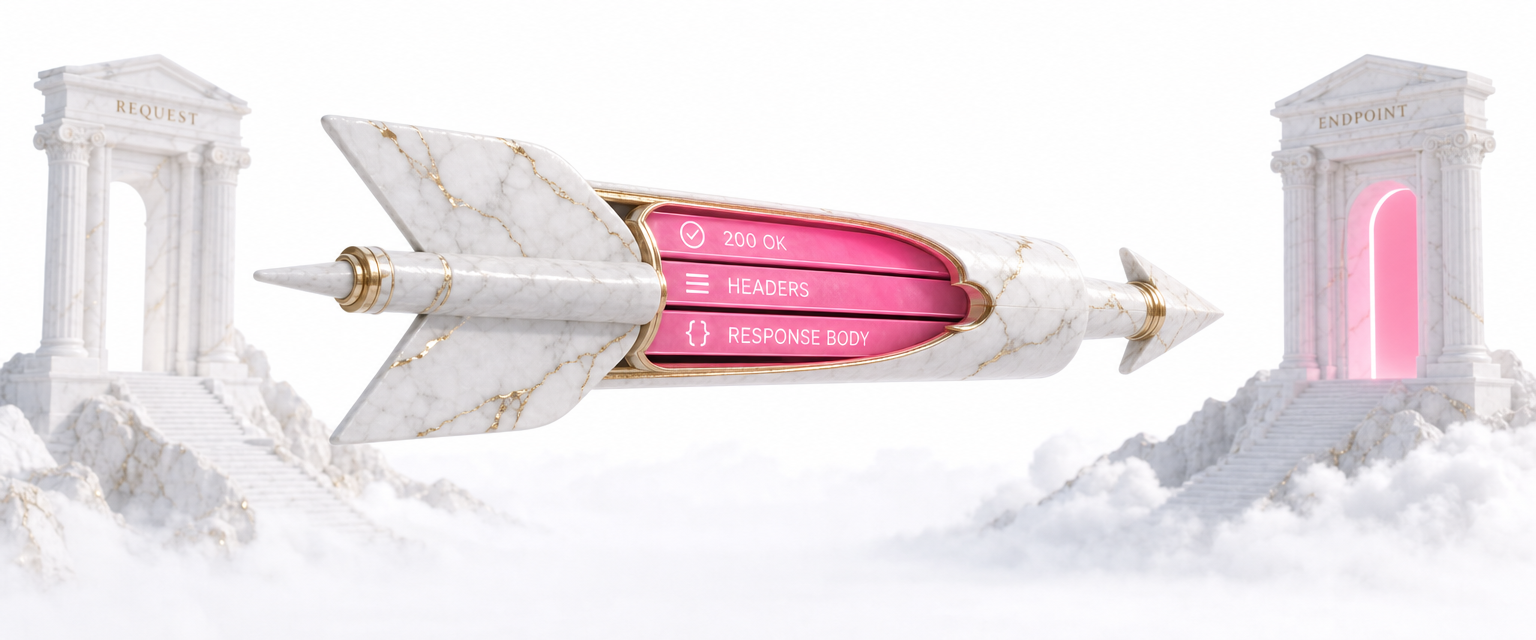
infsh/http
make an http request to a public url and get the status, headers and body back. json, form, text and multipart file uploads; internal addresses are refused.
openrouter/gemini-3-1-pro-preview
google's frontier reasoning model, with stronger coding and agentic reliability. 1m context; text, image, file, audio and video input.
openai/decisions
openai's decisions api on gpt-6 luna. send text and images with typed questions (choice, score, yes/no); get a probability for every answer in near real time, with no text generation. direct api.
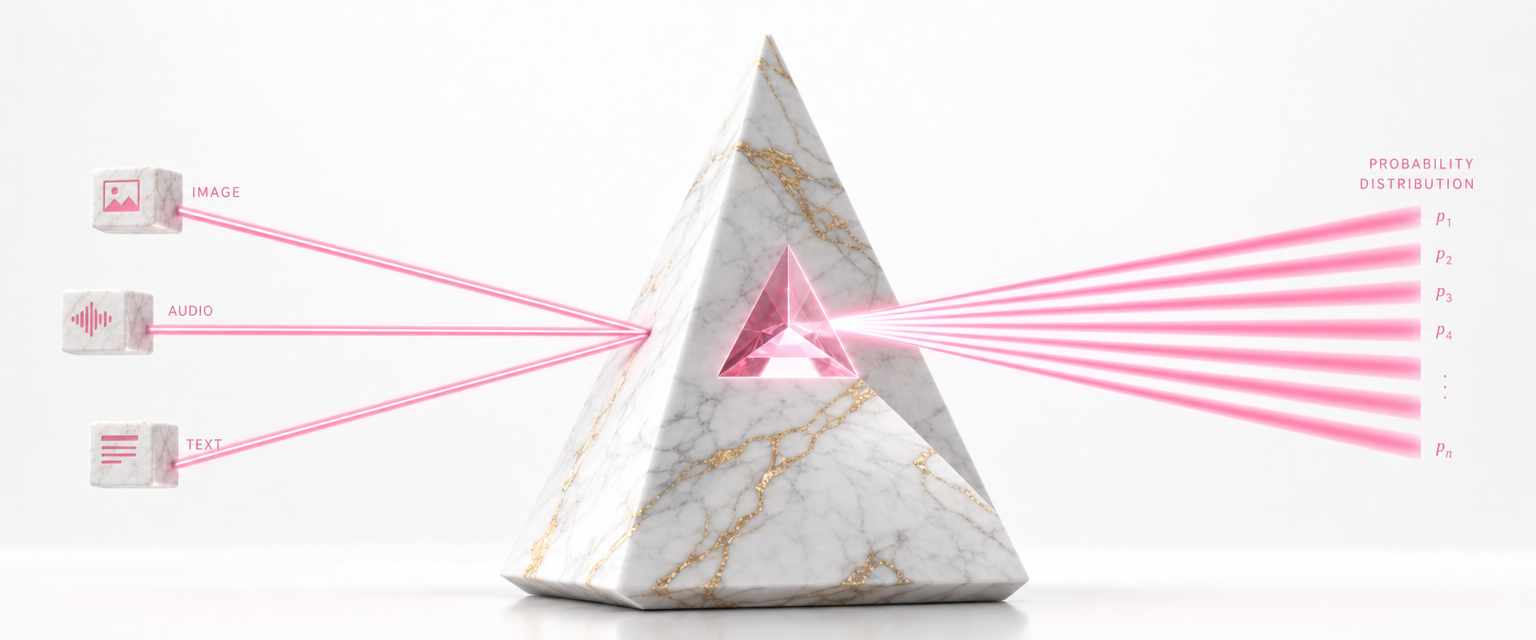
liquid/d1-omni-600m
liquid ai's 587m decision model for text, images and speech. send a state with images or an audio clip and typed questions (choice, score, yes/no); get a probability for every answer. research release
liquid/d1-3b
liquid ai's open 3b decision model for text and images. send a state and up to 8 images with typed questions (choice, score, yes/no); get a probability for every answer in one pass, no generation.
perplexity/decider-v1-1-27b
perplexity's open decision model for text and images. send a state, up to 4 images and typed questions (choice, score, yes/no); get a calibrated probability for every answer, with no text generation.
vllm-sr/decision-2-0-vega-27b
the largest decision 2.0 model from vllm semantic router. send a state and typed questions (choice, score, yes/no); get a probability for every answer in one pass. 29.37b parameters, 32k-token input.
autotrust/jev-27b-vl
autotrust's open decision model with vision. send text and up to 8 images with typed questions (choice, score, yes/no); get a calibrated probability for every answer, with no text generation.
google/gemini-nano-banana-2-1
gemini nano banana 2.1 via vertex ai — google's newest image model. better design, mask editing and subject consistency than nano banana 2, and faster. up to 4k, web search grounding.
vllm-sr/decision-2-0-lux-9b
the 9b decision 2.0 model from vllm semantic router. send a state and typed questions (choice, score, yes/no); get a probability for every answer in one forward pass, with no text generation. 7.94b parameters, 16,384-token input, about 18.4 ms per question.
vllm-sr/decision-2-0-nox-4b
the 4b decision 2.0 model from vllm semantic router. send a state and typed questions (choice, score, yes/no); get a probability for every answer in one forward pass, with no text generation. 4.21b parameters, 16,384-token input, about 12.9 ms per question.
vllm-sr/decision-2-0-sol-2b
the 2b decision 2.0 model from vllm semantic router. send a state and typed questions (choice, score, yes/no); get a probability for every answer in one forward pass, with no text generation. 1.88b parameters, 16,384-token input, about 7.2 ms per question.
vllm-sr/decision-2-0-eos-0-8b
a small, fast decision 2.0 model from vllm semantic router. send a state and typed questions (choice, score, yes/no); get a probability for every answer in one forward pass, with no text generation. 0.75b parameters, 16,384-token input, about 6.0 ms per question.
vllm-sr/decision-2-0-kai-0-6b
the smallest and fastest decision 2.0 model from vllm semantic router. send a state and typed questions (choice, score, yes/no); get a probability for every answer in one forward pass, with no text generation. 0.60b parameters, 8,192-token input, about 4.9 ms per question.
elevenlabs/eleven-flash-v2-5
elevenlabs eleven flash v2.5 text to speech. the fastest and lowest-cost elevenlabs model, for long texts and high volume.
elevenlabs/eleven-multilingual-v2
elevenlabs eleven multilingual v2 text to speech. stable, high-quality multilingual speech for long-form content.
elevenlabs/eleven-v3
elevenlabs eleven v3 text to speech. expressive speech in 70+ languages with audio tags for emotion and delivery.
elevenlabs/eleven-v4-turbo
elevenlabs eleven v4 turbo text to speech. the low-latency v4 model; send a text for an audio file, or stream text over a socket and hear it as it is written.
elevenlabs/eleven-v4
elevenlabs eleven v4 text to speech. the newest and most expressive model, with 90+ languages and audio tags; send a text for an audio file, or stream text over a socket and hear it as it is written.
openai/gpt-transcribe
transcribe speech with openai. send a recording and get its transcript from gpt transcribe, or stream a microphone over a socket and read the transcript as it is spoken with gpt live transcribe.
xai/grok-stt
transcribe speech with xai's grok speech to text. send a recording and get the transcript with word timings and speakers, or stream a microphone over a socket and read the transcript as it is spoken.
google/gemini-3-7-flash
gemini 3.7 flash via vertex ai — improved software engineering, web development and agentic workflows over 3.6 flash. 1m token context window.
google/gemini-3-8-flash
gemini 3.8 flash via vertex ai — google's most capable flash model, built for long-horizon software engineering, autonomous agents and complex enterprise workflows. 1m token context window.
melious/deepseek-v4-1-flash
deepseek v4.1 flash — 552b multimodal moe with 1m context, image input and controllable reasoning. frontier agentic and coding performance. via the melious api.
melious/minimax-m3
minimax m3 — 428b multimodal moe with 1m context and image input for long-horizon agentic, coding and cowork tasks. via the melious api.
melious/glm-5-3
glm 5.3 — zai's 744b moe post-trained for complex coding and long-horizon agentic tasks. 1m context, thinking on by default. via the melious api.
melious/kimi-k3
kimi k3 — moonshot's 2.8t open-weight multimodal agentic model with native vision and 1m context for long-horizon coding and reasoning. via the melious api.
melious/qwen3-6-27b
qwen 3.6 27b — dense 27b vision-language model with 262k context and thinking mode. strong coding and multimodal reasoning, apache 2.0. via the melious api.
melious/glm-5-3-flash
glm 5.3 flash — zai's 320b moe (18b active), the first natively multimodal glm-5 model. 1m context, image input, low cost. via the melious api.
melious/glm-5-2
glm 5.2 — zai's 744b moe with 1m context and hybrid reasoning for coding and agentic tasks. mit license. via the melious api.
not enough? create new apps fast. templates + coding agents make it insanely extensible.
start from templates. add code, packages, docs. deploy in minutes.
schemas become tool parameters automatically. your app shows up in the grid and can be used by agents and workflows.
build a graph of apps. deploy as a single callable app.
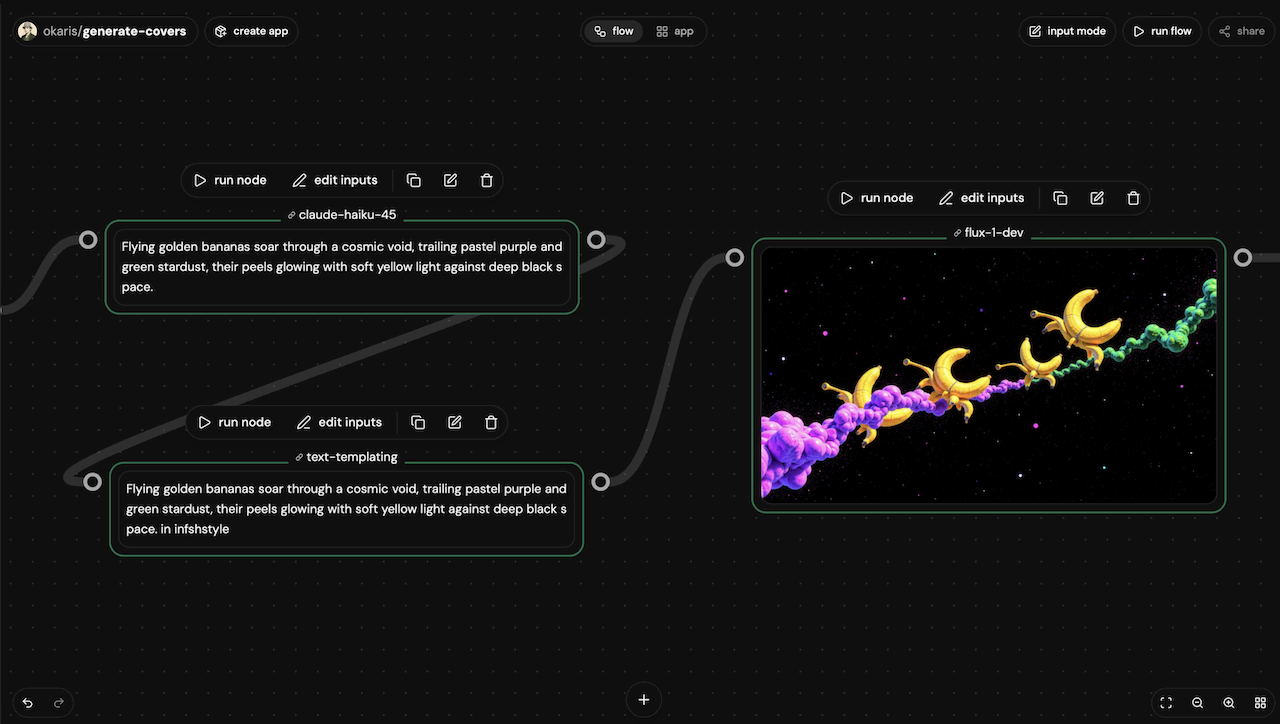
drag and drop to build the graph. map io to connect steps. deploy as an app.
three sources of apps
every app funnels into the same interface. where it comes from doesn't matter. same shape, same API.
hundreds of apps
image generation, video, audio, chat, search, and more. run any model with a single API call. pay per run, no subscriptions.
MCP servers
browse and add MCP servers. linear, notion, slack, github. your agent gets thousands of tools through the open standard.
flows become apps
chain any apps into a flow. the result is callable like any other app. AI models, non-AI apps, MCP servers, other flows. all composable.
also available as an MCP server
add one line to your MCP config. every app on inference shell becomes available to your agent.
{
  "mcpServers": {
    "inference": {
      "url": "https://api.inference.sh/mcp"
    }
  }
}
one api call
pruna/flux-dev · 7.9s · $0.005
sdks: javascript · python · go · cli
built to stay useful
same interface for every app. built-in or connected, same shape: input in, output out. no per-provider SDKs.
bring your own keys. route model runs through fal, google, or your own GPUs. you're not locked in.
every app run retries on failure, persists state, and tracks execution. built in, not bolted on.
an ai runtime where everything compounds. run any model, compose agents, stack knowledge. also includes a skill registry, MCP servers, and a team workspace.
start with the hosted platform. deploy your own when you're ready.
we use cookies
we use cookies to ensure you get the best experience on our website. for more information on how we use cookies, please see our cookie policy.
by clicking "accept", you agree to our use of cookies.
learn more.